Semantic Search aur Vector DB Guide: Haystack, Embeddings aur Cohere API
Introduction
Jab hum Google ya kisi search engine par kuch likhte hain, toh purane systems sirf exact words (keywords) match karte the. Lekin aaj ke modern AI systems sawal ke asli matlab (meaning/intent) ko samajh kar jawab nikalte hain. Is technology ko Semantic Search kehte hain.
Is comprehensive guide me hum seekhenge:
- Semantic Search kya hai aur iski kyu zaroorat hai?
- Semantic Search vs Keyword Search ka farq
- Semantic Search ka High-Level System Design & Implementation
- Document Handling, Chunking aur Embeddings
- Vector Database kaise kaam karta hai (Storing, Indexing & Query Matching)
- Haystack Framework aur Cohere API se Semantic Search banana
1. Semantic Search kya hai aur kyu zaroori hai?
Semantic Search ek aisi AI search technique hai jo exact spelling ya words match karne ke bajaye user ke sawal ke context aur meaning (bhav) ko samajhti hai.
Example: Agar user search kare: “Gadi start nahi ho rahi, kya karu?”
- Keyword Search: Aise articles dhundega jisme exact word “gadi” ya “start” ho.
- Semantic Search: Samajh jayega ki problem car battery, ignition ya engine troubleshooting se judi hai aur sabse relevant mechanics guide dikhayega.
Applications of Semantic Search:
- E-Commerce Search: “Office pehanne layak sasti shirt” search karne par formal shirts dikhana.
- Enterprise Document Search: Company ke lakho internal PDFs/Policies me se exact answer nikalna.
- Customer Support Bots: User ki tooti-footi bhasha se problem identify karke solution dena.
- Legal & Medical Search: Medical reports aur kanooni dastavez me se matching case laws retrieve karna.
2. Semantic Search vs Keyword Search (Comparison)
| Feature | Keyword Search (Lexical) | Semantic Search (Vector/Neural) |
|---|---|---|
| Search Basis | Exact words / spelling match | Meaning, context aur user intent |
| Synonyms Handling | Manual synonym dictionary chahiye | Automatically samajhta hai (Car = Gadi = Vehicle) |
| Typo Tolerance | Spelling galti par fail ho sakta hai | Meaning samajh kar sahi result deta hai |
| Multi-lingual Support | Ek bhasha tak seemit | Cross-lingual search possible (Hinglish/English mix) |
| Technology | BM25, TF-IDF, Elasticsearch | Embeddings, Vector DBs (FAISS, Pinecone, Qdrant) |
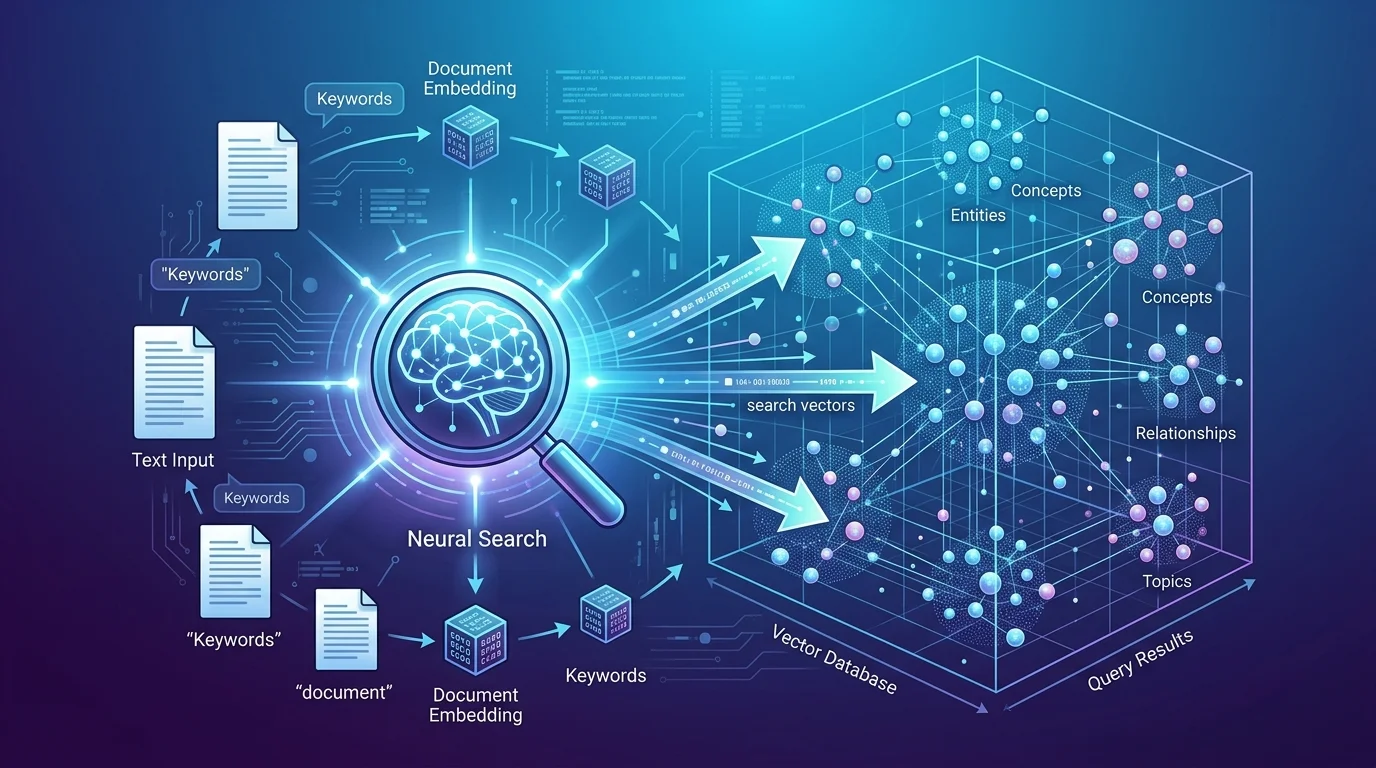
3. High-Level Design (HLD) of Semantic Search
Semantic Search ka architecture 2 main phases me kaam karta hai:
=== Phase 1: Data Ingestion & Indexing Pipeline ===
[ Raw Documents (PDFs, Docs, Web) ]
                │
                ▼ (1. Data Cleaning & Document Parsing)
[ Clean Plain Text ]
                │
                ▼ (2. Chunking / Splitting)
[ Chunks (e.g. 500 characters + overlap) ]
                │
                ▼ (3. Embedding Model / Cohere / HuggingFace)
[ Vector Arrays: [0.12, -0.45, 0.89, ...] ]
                │
                ▼ (4. Storage & Indexing)
[ Vector Database (Chroma / Pinecone / Qdrant) ]

=== Phase 2: Search & Retrieval Pipeline ===
[ User Query: "How to claim health policy?" ]
                │
                ▼ (Embed Query via same model)
[ Query Vector: [0.11, -0.42, 0.85, ...] ]
                │
                ▼ (5. Similarity Search / Cosine Distance)
[ Vector DB Index (HNSW / IVF) ]
                │
                ▼ (6. Ranker / Top-K Chunks)
[ Final Relevant Results to User / LLM ]
4. Document Handling, Chunking aur Embeddings
A. Handling Raw Documents
Raw files me headers, footers, images aur HTML tags hote hain. Inhe pehle clean text me convert kiya jata hai (tools like Unstructured ya PyPDF).
B. Chunking kyu zaroori hai?
Embedding models ek bar me poori 100-page ki PDF ko theek se process nahi kar sakte. Isliye document ko chote Chunks me toda jata hai.
- Chunk Size: Aam taur par 250 se 1000 tokens.
- Chunk Overlap (e.g., 10-20%): Do chunks ke beech thoda common text rakha jata hai taaki kisi sentence ka context beech me na toot jaye.
[ Document: "Ahmad is a software engineer. He works on AI systems in Bangalore." ]
Chunk 1: [ Ahmad is a software engineer. He works on AI ]
Chunk 2: [ He works on AI systems in Bangalore. ] (Overlap maintains context)
C. Embeddings (Vector Representations)
Embedding Model text ko numbers ke ek fixed array (vector) me badal deta hai (e.g., 768 ya 1536 dimensions).
- Jitne paas do words ya sentences ka matlab hoga, unke vectors ke beech ka distance utna kam hoga.
5. Vector Database kaise kaam karta hai?
Normal databases (SQL/PostgreSQL) text ko match karne ke liye b-tree indexes use karte hain. Lekin Vector Database high-dimensional numbers ke beech mathematical distance measure karta hai.
1. Storing & Indexing
Vector DB har chunk ke text, metadata aur uske vector embeddings ko store karta hai.
- ANN (Approximate Nearest Neighbors): Lakho vectors me se fast search karne ke liye algorithms use hote hain jaise:
- HNSW (Hierarchical Navigable Small World): Super-fast graph-based search.
- IVF (Inverted File Index): Vectors ko clusters me baant kar search speed badhata hai.
2. Query Matching (Similarity Metrics)
Jab user search karta hai, Vector DB query vector aur stored vectors ke beech similarity calculate karta hai:
| Metric | Formula Logic | Kab Use Karein? |
|---|---|---|
| Cosine Similarity | Vectors ke beech ka angle check karta hai (-1 to +1). | Text similarity ke liye sabse popular aur reliable. |
| Dot Product | Magnitude aur direction dono ko measure karta hai. | Normalized embeddings me fast computation ke liye. |
| Euclidean Distance (L2) | Do points ke beech ki direct geometrical doori. | Numerical distance check karne ke liye. |
6. Semantic Search using Haystack & Cohere API
Haystack (by deepset) ek modern open-source framework hai jo specifically Semantic Search aur RAG pipelines ke liye banaya gaya hai.
Haystack ke Main Features:
- Modular Pipelines: Preprocessors, Document Stores, Retrievers aur Rankers ko aapas me jodna.
- Vector DB Connectors: Pinecone, Qdrant, Elasticsearch, Chroma, Weaviate sabhi ke sath direct compatibility.
- Extractive & Generative QA: Answer extract bhi kar sakta hai aur LLM se generate bhi.
Cohere API:
Cohere enterprise-grade AI models deta hai jo semantic search ke liye industry me top maane jate hain:
- Cohere Embed (
embed-multilingual-v3.0): 100+ bhashao me powerful embeddings. - Cohere Rerank (
rerank-v3): Vector search ke baad results ko re-order karke top relevant answer nikalna.
Implementation Example (Haystack 2.x Pipeline):
from haystack import Document, Pipeline
from haystack.document_stores.in_memory import InMemoryDocumentStore
from haystack.components.embedders import SentenceTransformersDocumentEmbedder, SentenceTransformersTextEmbedder
from haystack.components.retrievers.in_memory import InMemoryEmbeddingRetriever

# 1. Document Store Setup
document_store = InMemoryDocumentStore()

# 2. Documents
docs = [
    Document(content="Term life insurance plan provides financial security to family."),
    Document(content="Health insurance covers hospitalization expenses and medical tests."),
    Document(content="Motor insurance protects your car and two-wheeler from damages.")
]

# 3. Indexing Pipeline
indexing_pipeline = Pipeline()
indexing_pipeline.add_component("embedder", SentenceTransformersDocumentEmbedder(model="sentence-transformers/all-MiniLM-L6-v2"))
indexing_pipeline.add_component("writer", DocumentWriter(document_store=document_store))
indexing_pipeline.connect("embedder", "writer")
indexing_pipeline.run({"embedder": {"documents": docs}})

# 4. Query Pipeline
query_pipeline = Pipeline()
query_pipeline.add_component("text_embedder", SentenceTransformersTextEmbedder(model="sentence-transformers/all-MiniLM-L6-v2"))
query_pipeline.add_component("retriever", InMemoryEmbeddingRetriever(document_store=document_store))
query_pipeline.connect("text_embedder.embedding", "retriever.query_embedding")

# 5. Semantic Search Run
query = "Doctor bill aur hospital coverage plan"
result = query_pipeline.run({"text_embedder": {"text": query}})

for doc in result["retriever"]["documents"]:
    print(f"Match: {doc.content} (Score: {doc.score})")
7. Quick Revision Summary
- Semantic Search: Words ke bajaye ‘intent/meaning’ se search karta hai.
- Chunking + Overlap: Bade documents ko chote context-preserving pieces me todna.
- Embeddings: Text ka numerical vector representation (meaningful numbers).
- Vector DB: High-dimensional vectors ko HNSW/IVF indexing aur Cosine similarity se search karne wala database.
- Haystack: Production-ready semantic search aur RAG pipelines banane ka framework.
- Cohere: Best-in-class multilingual embeddings aur reranking API service.